The Best AI Models for Coding in 2026, Tested Against Real Tasks
Claude, GPT-5, Gemini, and Grok compared on real coding work -- refactoring, debugging, and greenfield generation -- not just benchmark scores.
Deelo Editorial
Benchmark leaderboards change every few weeks, and none of them tell you which model will actually make your Tuesday afternoon debugging session shorter. This is a comparison built around the tasks developers actually do — reading an unfamiliar codebase, refactoring something without breaking it, debugging a failure that doesn't reproduce cleanly, and generating new code from a spec — rather than a single aggregate score.
Why benchmark rank isn't the same as "best for you"
SWE-bench, the benchmark most coding-model comparisons lead with, measures whether a model can resolve real GitHub issues autonomously. It's a reasonable proxy for agentic capability, but it rewards a narrow slice of what coding work actually involves: closed, well-specified bugs in popular open-source repos. It says very little about how a model performs on a 200,000-line internal codebase with inconsistent conventions, or how well it explains its reasoning when you need to sanity-check a suggestion before merging it.
Two models within two points of each other on SWE-bench can feel completely different to work with — one might front-load a wall of caveats before every answer, another might quietly change five unrelated files while fixing the one you asked about. That difference matters more day to day than a percentage point.
The four models worth comparing right now
Claude (Opus and Sonnet tiers). Claude's edge is in tasks that require holding a lot of context correctly: multi-file refactors, tracking type dependencies across module boundaries, and understanding why a codebase is structured the way it is before changing it. It's also the model underneath the two most widely used AI coding editors, which says something about how it performs in agentic, tool-using workflows rather than single-turn chat. The tradeoff is cost — the higher-reasoning tiers aren't the cheapest per token, and for simple, high-volume tasks that expense adds up.
GPT-5 tiers. OpenAI's current generation is a strong generalist choice, and testing consistently shows it near the top on real GitHub issue resolution — the closest thing to "will this actually fix the bug, not just something that looks like a fix." It tends to be a good default for teams that want one model across coding, docs, and general reasoning rather than switching tools by task.
Gemini. Gemini's differentiator is context window size — the ability to load an entire mid-sized codebase, or a full dependency tree, in one prompt without chunking it manually. If your bottleneck is "the model doesn't have enough of the codebase in view to reason correctly," Gemini solves that in a way token-limited alternatives can't. It's a weaker pick when the task is a small, isolated fix where context size isn't the constraint.
Grok and open-weight alternatives. Grok has closed the benchmark gap on raw coding tasks and is worth testing if your workflow is API-driven and cost-sensitive. Open-weight models (Qwen, DeepSeek, and similar) have gotten good enough that they're a legitimate option for teams that need to self-host for compliance reasons, though they generally lag the frontier closed models on the hardest agentic tasks — long multi-step tool use where the model has to recover from its own mistakes.
What benchmark methodology actually measures
It's worth understanding what SWE-bench and similar suites reward, because it explains why leaderboard rank and real-world feel diverge. Most of these benchmarks pull issues from popular open-source repositories with active maintainers, clear reproduction steps, and existing test suites. That's a reasonable stand-in for "can this model fix a well-documented bug," but it under-represents three things that dominate real engineering work: codebases with inconsistent or undocumented conventions, tasks where the fix requires a product or business judgment call rather than a purely technical one, and long-running agentic sessions where a model has to notice and correct its own earlier mistake without a human pointing it out. A model can top a benchmark built on the first kind of task and still struggle with the second and third — which is why the practical comparison in this piece leans on task category rather than a single score.
Breaking it down by the kind of work you actually do
Frontend and UI work tends to reward models with strong visual and component-library reasoning — understanding how a design system's conventions should extend to a new component, not just producing syntactically valid JSX. Gemini and GPT-5 tiers have both closed the gap here relative to a year ago; the differentiator is usually how well the model infers your project's existing patterns rather than defaulting to a generic implementation.
Backend and API work is where reasoning depth pays off most directly — data modeling decisions, race conditions, and edge cases in business logic are exactly the kind of ambiguous, multi-constraint problems where a stronger reasoning tier earns its cost.
Infrastructure and DevOps tasks — Terraform, CI configuration, deployment scripts — are unusually punishing for AI-assisted work because a subtly wrong change often doesn't fail until it's already running in production. This is a category where the discipline of full-diff review matters more than which model wrote the change, because the failure mode isn't a compile error, it's a 2 a.m. page.
Legacy code maintenance — the least glamorous and most common category — rewards whichever model handles large context most faithfully, since the real cost is usually understanding what a decade of undocumented decisions actually did, not writing new code.
Data handling and where models run
For teams working with proprietary or regulated codebases, which model is "best" also depends on where your code and prompts actually go. Hosted frontier models process requests on the provider's infrastructure under whatever data-retention terms are in your enterprise agreement; open-weight models can be self-hosted, which trades some raw coding capability for full control over where the code physically lives. If you're in a regulated industry or your codebase includes anything you can't send to a third party under your compliance posture, that constraint should filter your model choice before benchmark scores ever enter the conversation — a strong model you can't legally use isn't actually an option.
Match the model to the task, not the leaderboard
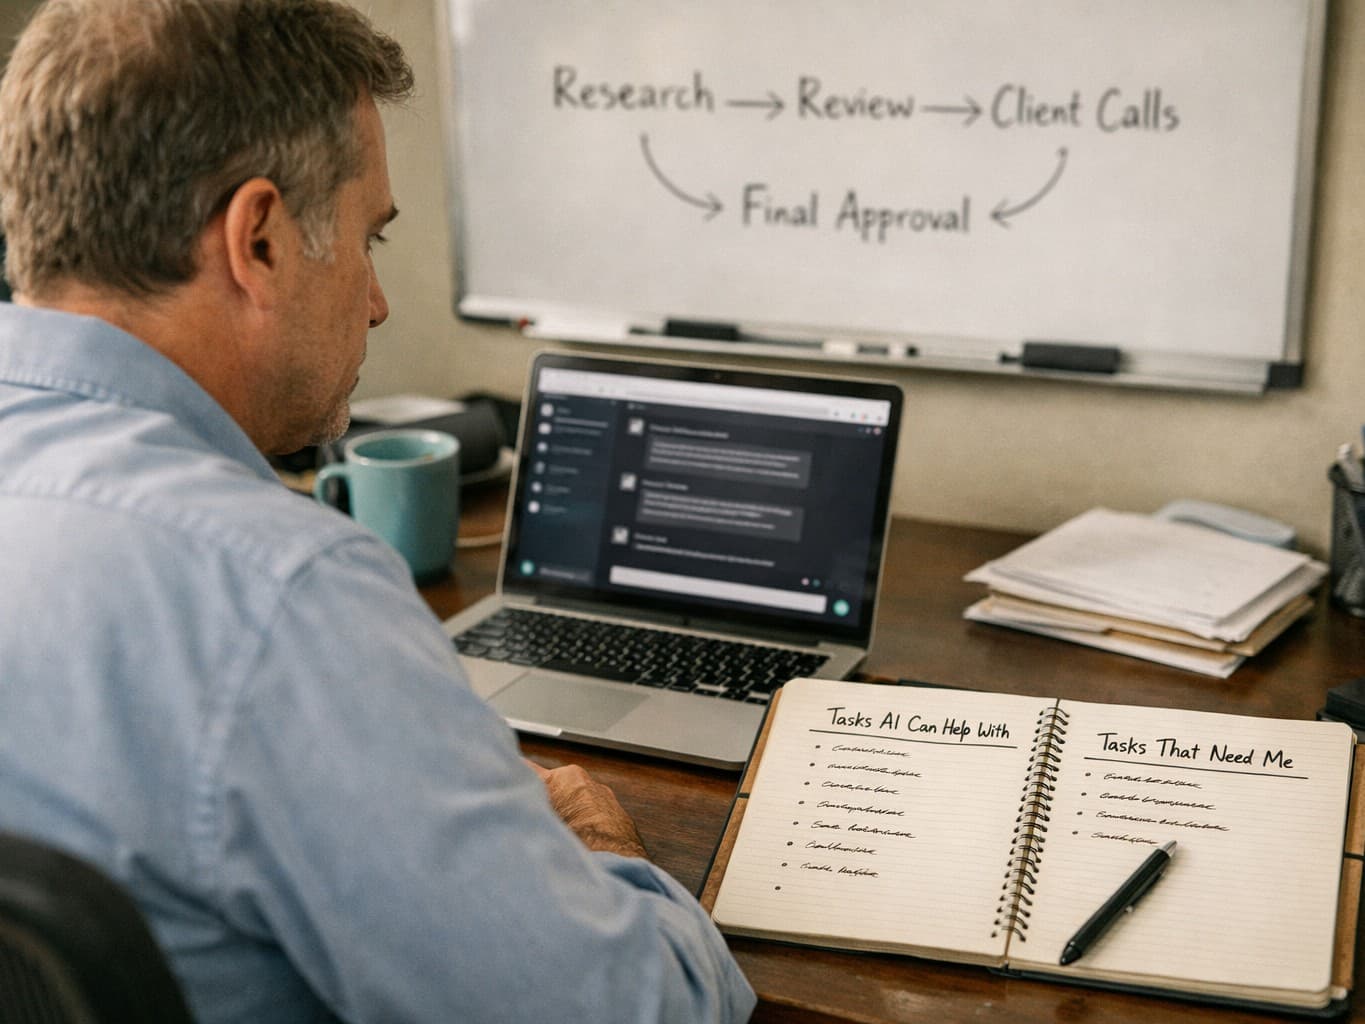
The most productive setups in 2026 don't pick one model and stop — they route different kinds of work to different models, the same way a team routes a quick Slack question differently than a design doc:
- First-pass generation on a well-specified task — a fast, cheaper model is usually fine. You're going to review the output anyway.
- Debugging something that doesn't reproduce reliably — spend the extra latency on the strongest reasoning tier available. This is where cheaper models most often produce a plausible-looking fix that doesn't actually address the root cause.
- Large-scale refactors across many files — favor whichever model handles the most context accurately, and treat the diff review as non-negotiable regardless of which model wrote it.
- Reading a codebase you didn't write — a large context window earns its cost here in a way it doesn't for a 20-line function.
This is the same logic as choosing an AI model for any workflow: name the constraint that actually matters for the task in front of you — speed, cost, reasoning depth, or context size — before comparing benchmark tables.
Solo developers vs. teams need different setups
A solo developer optimizing for speed can reasonably default to a single strong general model and switch only when a specific task type clearly benefits from something else — the overhead of juggling multiple subscriptions and remembering which model is better at what isn't worth it below a certain scale.
Teams face a different calculus. Standardizing on one model organization-wide makes code review predictable — reviewers learn to recognize that model's typical failure patterns, which speeds up review over time. But a team large enough to have distinct frontend, backend, and infra specialists often gets more value from letting each sub-team pick the model best suited to its task category, accepting the small cost of less-uniform review patterns in exchange for better task fit. There's no universally correct answer here — it's a real tradeoff between standardization and task fit, and the right side of it depends on team size more than anything else.
What actually predicts a bad outcome
Across real teams, the failure mode isn't usually "the model was too weak." It's one of three things:
- Under-specified prompts. A model asked to "fix the bug" with no reproduction steps or expected behavior will often produce something that compiles and looks reasonable, which is worse than an obvious failure because it passes a cursory glance.
- Skipped diff review. Every model, including the strongest ones, will occasionally touch a file it wasn't asked to touch, or make a change that's technically correct but stylistically inconsistent with the rest of the codebase. Reviewing the full diff — not just the part you expected to change — catches this before it ships.
- Using an agentic workflow for a task that didn't need one. Letting a model run multiple tool calls autonomously is powerful for well-bounded tasks and risky for ambiguous ones, where it can spend a long time confidently going in the wrong direction before a human notices.
Cost is a real constraint, not an afterthought
Subscription and API pricing for the frontier tiers isn't trivial once you're running them daily across a team, and it's worth treating as a real line item rather than an unexamined recurring charge. If you're budgeting software spend the way the 50/30/20 rule treats recurring subscriptions — as a "wants" or discretionary line, not a fixed need — a coding-assistant subscription is a good candidate to actually evaluate against the time it saves rather than renewing on autopilot. For a solo developer or small team, that often means one strong general model as the default and selective use of a second model only for the specific task type where it clearly outperforms — not three parallel subscriptions maintained out of habit.
Switching costs are real, and worth naming honestly
Every model has its own conventions for how it structures multi-step tasks, how verbose it is by default, and how it prefers to be prompted for agentic work versus a single-turn question. Moving a team's workflow from one model to another isn't free — expect a week or two of recalibrating prompts and internal documentation before a new model's output quality matches what the team had tuned the old one to produce. That's not a reason to avoid switching when a genuinely better fit exists, but it is a reason not to chase every incremental leaderboard shift. A model that's 2% ahead on a benchmark this month rarely justifies the transition cost of moving an entire team's workflow to it.
A simple decision framework
If you only have time to pick one model, ask three questions in order:
- Does the task require holding a large amount of context accurately? If yes, prioritize context window size and multi-file coherence over raw benchmark rank.
- Is the task ambiguous, or does it require judgment about tradeoffs? If yes, prioritize the strongest available reasoning tier, even at higher cost and latency — this is where weaker models produce confident-but-wrong output.
- Is the task simple, well-specified, and high-volume? If yes, use the fastest and cheapest model that reliably handles it, and save the expensive tier for the 20% of tasks that actually need it.
None of the four models above is strictly "best" — they're differently shaped tools, and the benchmark gap between the top three on any given week is usually smaller than the gap between using the right model well and using any model carelessly.